// HACKER NEWS — CYBERSECURITY
What Is RLCD? The Secret Behind Jev
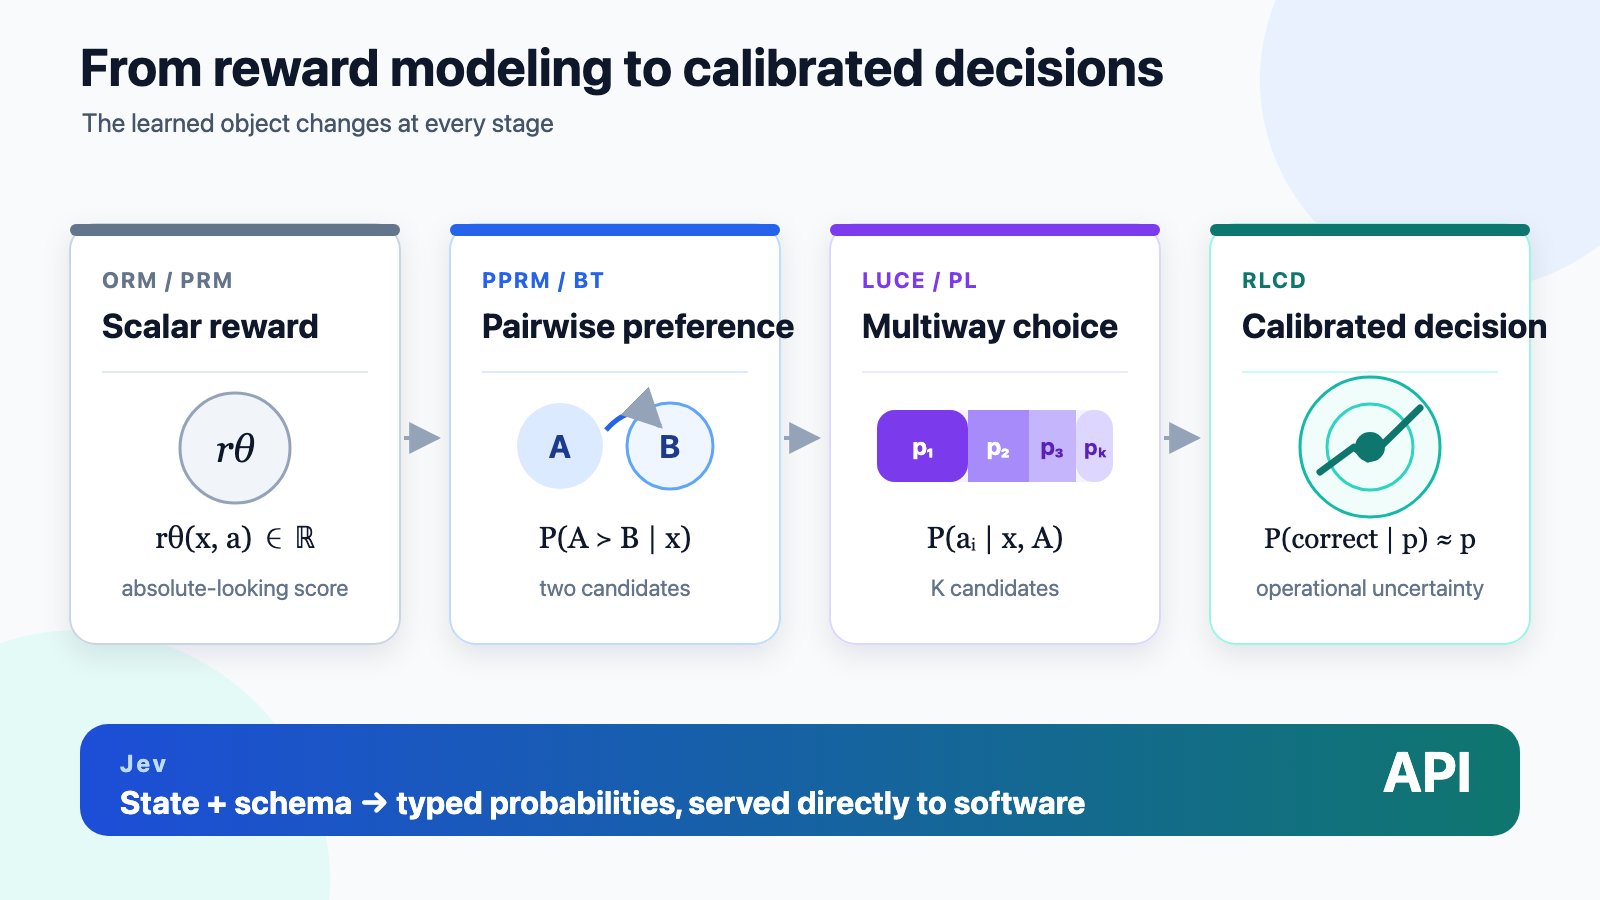
From pairwise reward modeling to calibrated, multiway decisions
Jev looks mysterious when viewed as an alternative to a language model. It becomes much simpler when viewed as the next step in reward modeling.
More specifically, RLCD is a schema-conditioned Plackett–Luce objective. Jev turns that objective into a product by adding typed outputs and parallel inference.
That is the secret: the reward model is no longer hidden behind a generator. The reward model becomes the model.
A conventional reward model receives a context \(x\) and a candidate answer \(a\), then produces a scalar:
Outcome reward models score the final answer. Process reward models score individual reasoning steps. In both cases, the learned object is an absolute-looking number.
The problem is that this number is not actually absolute.
A reward of \(0.8\) does not have a stable meaning across problems, candidate pools, checkpoints, or model families. It is mainly useful for comparing candidates generated under similar conditions:
The operational signal was always relative preference. The scalar merely hid it.
LLaMA-Berry’s Pairwise Preference Reward Model, or PPRM, exposes the comparison directly.