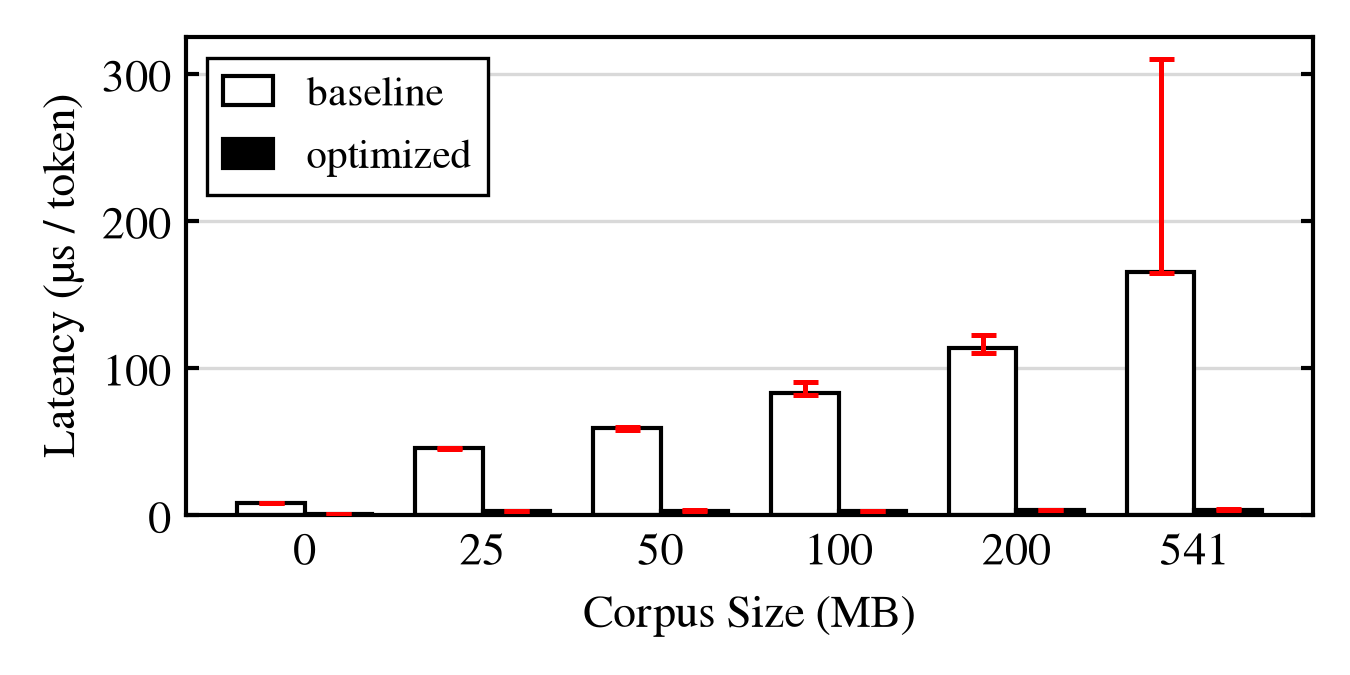
// HACKER NEWS — CYBERSECURITY Faster prompt lookup drafting in llama.cpp Published: 09/26/2026, 07:57 PM Four changes to the n-gram caches of llama.cpp make drafting up to 41.6x faster, load the static cache up to 23.5x faster, and lower peak memory up to 2.65x.