// HACKER NEWS — CYBERSECURITY
Language models for text classification: From bag-of-words to Jev
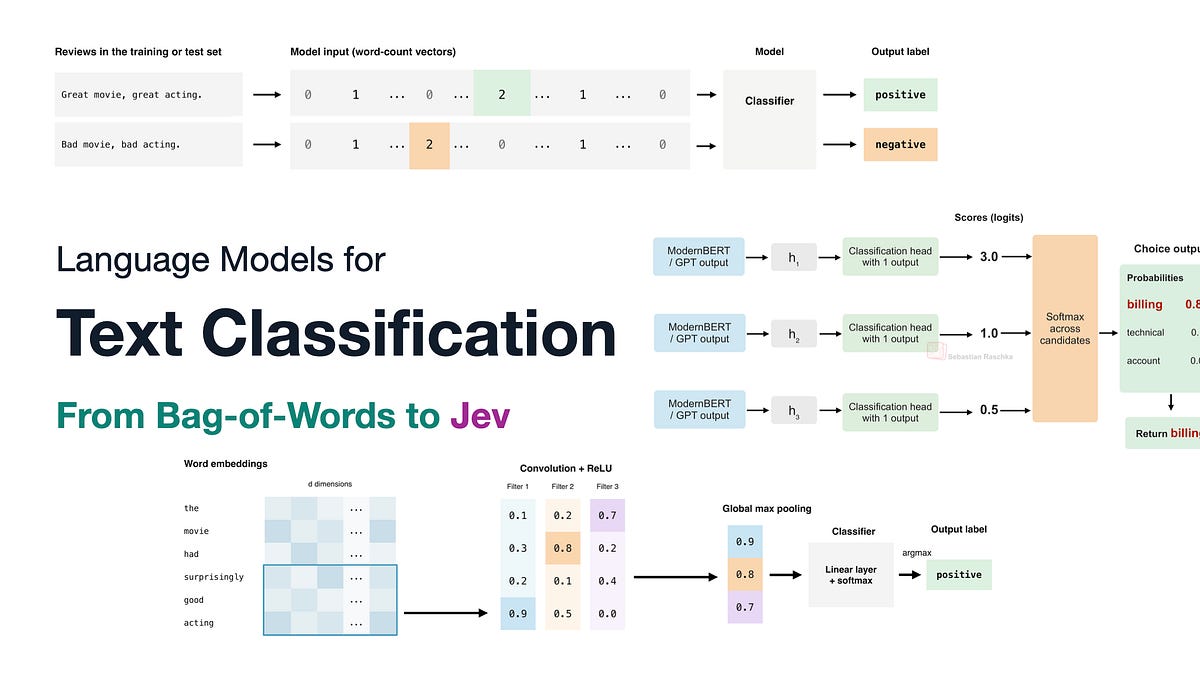
The recently released Jev AI model has been quite a cultural phenomenon in technical communities in the past 2 weeks.
While Jev aims to classify things, it’s easy to dismiss Jev as “just a classifier,” and my own view of Jev has evolved quite a bit over the past few days. In particular, my thoughts went from “classifiers used to be my bread & butter; I can easily build this myself” (more on this later) to “wow, this actually works better than I thought.”
Sure, the latest state-of-the-art GPT and open-weight LLMs can do the same kinds of classification tasks as Jev, while also being capable of much more general decision-making. But Jev’s advantage is that it can handle those classification tasks much faster and more cheaply.
At the other end of the spectrum, for a narrow, well-defined problem, Jev probably won’t classify anything better, faster, or cheaper than a special-purpose classifier. But its selling point is that it is far more general than those task-specific models.
So, what is the methodology behind Jev (based on an educated guess), what can it do, and why is it so popular? I aim to answer all of these later in this article. However, I thought starting with a brief history of language models for decision-making would be a great way to begin. And it hopefully helps demystify some of the hype and show what Jev does very well (”Jev is essentially a text classifier,” but “Jev is also not ‘just’ a text classifier.”)
PS: I am not affiliated with Jev in any way. Also, I am not offered free access to Jev, and this is also not a product endorsement, just a technical article to offer some insights into the history of text classification to help you make sense of the recent hype.
Since this is a long article, I recommend reading it in your browser, where you can access the table of contents menu on the left side.
For completeness, before we put Jev in context (no pun intended), I thought it made the most sense to start chronologically. In this section, I want to take a brief tour of applied text classification via naive Bayes, logistic regression, and the more classic (deep) neural networks before transformer-based models came along.
Back in the day, when I was a grad student 15 years ago, even though recurrent neural networks already existed (more on that later), text classification was usually done with a bag-of-words representation because it was straightforward and could get good results on moderately sized datasets.
In short, we can think of the bag-of-words representation as a method that makes free-form text input of different lengths compatible with classic classifiers (naive Bayes, Logistic Regression, SVMs, Random Forest, XGBoost, to name a few), which expect a fixed-size input vector.